Method
Perceive. Describe. Act.
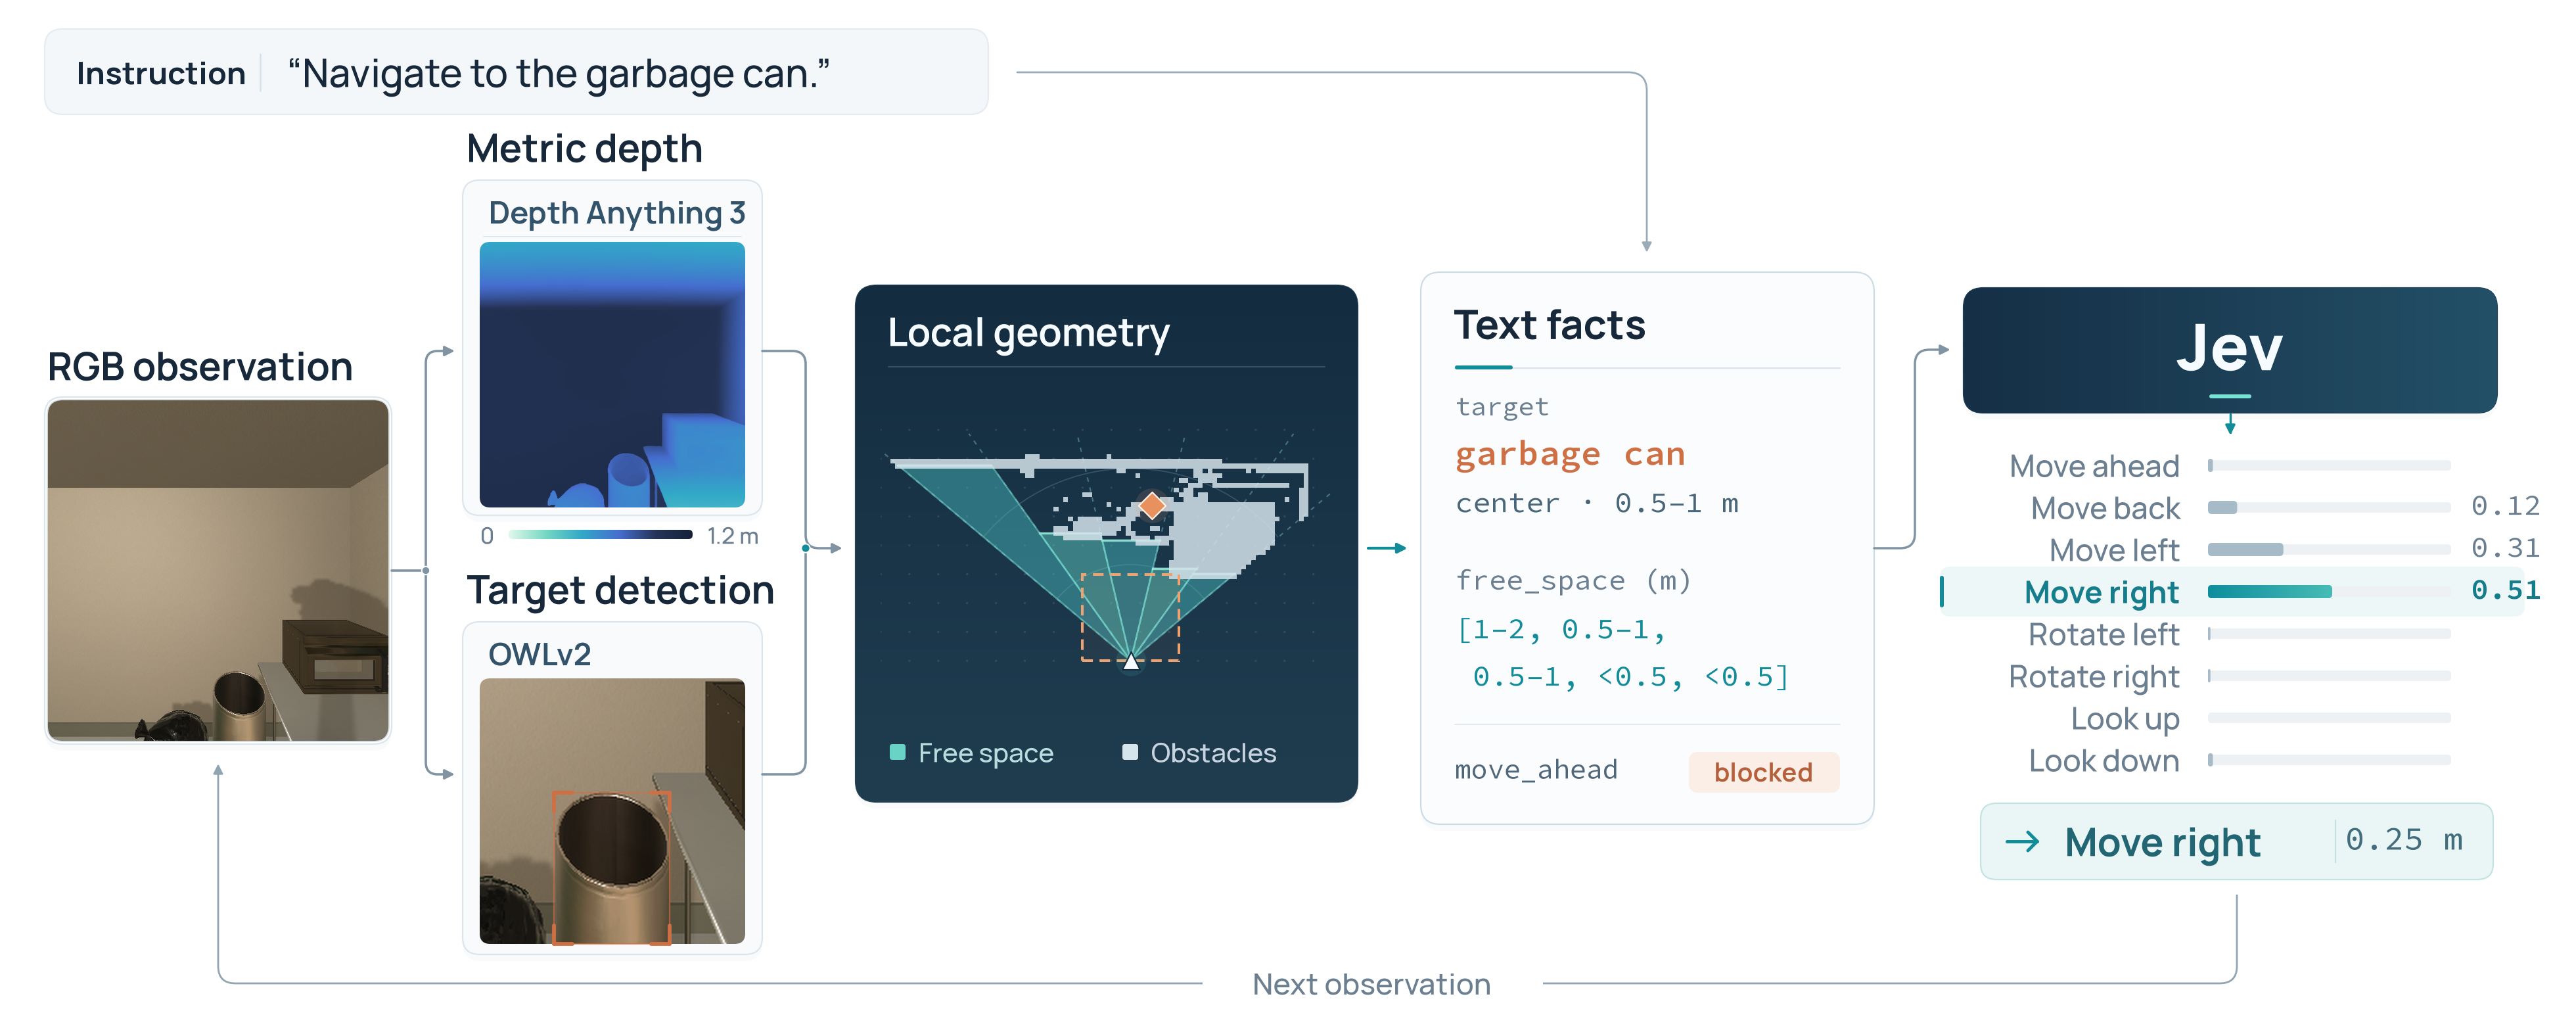
Monocular metric depth and open-vocabulary detection become a compact, metre-level description of the scene. Jev reasons over that description and returns one of eight navigation actions.
1
👁️
Perceive
Depth Anything 3 estimates metric depth; OWLv2 finds the target in the frame.
2
📝
Describe
Free space in five sectors, a 0.25 m collision check, target distance and recent actions become text facts.
3
🎯
Act
Jev reads the facts, picks one action, and the loop repeats with the next observation.